20 Open-Source Repos to Cut Agent Spend at the Four Leak Points
Core engineering thesis: Agent swarms don’t go broke on intelligence—they bleed tokens on two silent leaks: reading raw layouts/logs the task never needed and recomputing finished work. Diagnose your exact leak below to generate a minimal 3–4 repo starter stack instead of installing all 20 on Day 1.
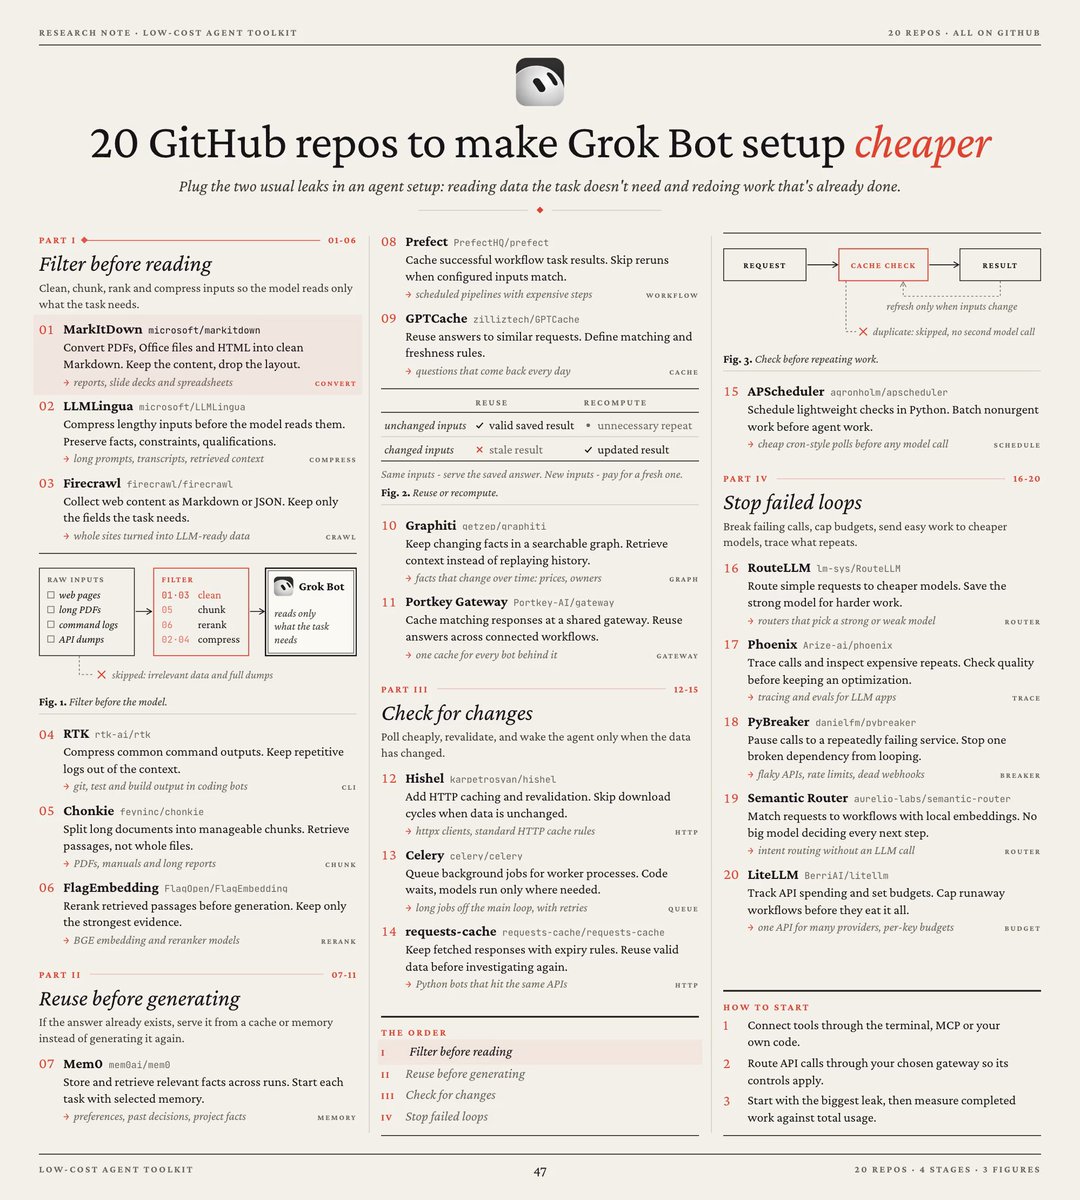
Shrinking Token-Leak Funnel (Execution Order)
FIG.01 · WATERFALLInteractive Symptom → Minimal Starter Stack
DIAGNOSTIC| # | Tool | Stage | Exact Leak Eliminated | GitHub Repository |
|---|---|---|---|---|
| 01 | MarkItDown | I · FILTER | Converts PDFs, Office docs & HTML to clean Markdown (drops layout junk). | microsoft/markitdown ↗ |
| 02 | LLMLingua | I · FILTER | Compresses long prompts & transcripts while preserving task-critical facts. | microsoft/llmlingua ↗ |
| 03 | Firecrawl | I · FILTER | Scrapes sites into clean Markdown/JSON keeping only fields the agent needs. | firecrawl/firecrawl ↗ |
| 04 | RTK | I · FILTER | Compresses noisy CLI output (git, tests, build logs) before context injection. | rtk-ai/rtk ↗ |
| 05 | Chonkie | I · FILTER | Splits manuals & reports cleanly so retrieval pulls paragraphs, not whole PDFs. | feyninc/chonkie ↗ |
| 06 | FlagEmbedding | I · FILTER | Reranks retrieved chunks pre-generation so weak matches never burn tokens. | flagopen/flagembedding ↗ |
| 07 | Mem0 | II · REUSE | Pulls selective learned memory across runs instead of replaying full history. | mem0ai/mem0 ↗ |
| 08 | Prefect | II · REUSE | Caches finished workflow task outputs and skips rerun when inputs match. | prefecthq/prefect ↗ |
| 09 | GPTCache | II · REUSE | Serves saved answers to semantically similar prompts with configurable TTL. | zilliztech/gptcache ↗ |
| 10 | Graphiti | II · REUSE | Tracks changing entities (prices, owners) in a temporal graph vs. raw logs. | getzep/graphiti ↗ |
| 11 | Portkey Gateway | II · REUSE | Central AI gateway sharing cached responses across every bot in a swarm. | portkey-ai/gateway ↗ |
| 12 | Hishel | III · POLL | Adds RFC HTTP caching/304 revalidation to httpx so unchanged endpoints sleep. | karpetrosyan/hishel ↗ |
| 13 | Celery | III · POLL | Moves waiting, retries & dispatch onto cheap queues outside LLM calls. | celery/celery ↗ |
| 14 | requests-cache | III · POLL | Persists Python HTTP responses with expiry before waking an agent. | requests-cache/requests-cache ↗ |
| 15 | APScheduler | III · POLL | Runs lightweight cron checks in plain Python & batches non-urgent diffs. | agronholm/apscheduler ↗ |
| 16 | RouteLLM | IV · CAP | Sends simple tasks to cheap models; reserves frontier models for hard steps. | lm-sys/routellm ↗ |
| 17 | Phoenix | IV · CAP | Traces agent runs to expose repeated calls & verify quality before cutting cost. | arize-ai/phoenix ↗ |
| 18 | PyBreaker | IV · CAP | Trips circuit breaker on flaky APIs to stop runaway retry billing loops. | danielfm/pybreaker ↗ |
| 19 | Semantic Router | IV · CAP | Routes user intents via fast local embeddings instead of LLM tool-selection. | aurelio-labs/semantic-router ↗ |
| 20 | LiteLLM | IV · CAP | Enforces hard per-key dollar spend limits across providers before runaway bills. | berriai/litellm ↗ |
4-Step Rollout Discipline
SOP1. Trace First (Phoenix + LiteLLM): Measure real token spend and set hard dollar caps before optimizing.
2. Single Gateway: Route all bots through Portkey or LiteLLM so caching/budgets actually apply.
3. Plug #1 Leak First: Use the diagnostic checklist above—never deploy 20 libraries on Day 1.
4. Count Infra Overhead: Track embedding/worker costs alongside token savings per finished task.
Verification & Fact Boundary
AUDITHeadline anecdote unverified: The viral hook (“300 Grok bots at <$0.02/bot/wk vs. $4,500/wk”) is reported in Iron Giant’s post without a public invoice audit.
All 20 repos verified real: Every linked repo above is an established open-source library across Microsoft, Prefect, Zilliz, Arize, Mem0, Portkey, and LiteLLM.